new

Get trending papers in your email inbox!

Subscribe

Trending Papers

byAK and the research community

Trending Papers
Submitted by
aaronjli

TokenEconomizer: Experience-Driven Black-Box Cost Control for Coding Agents

TokenEconomizer reduces recurring token costs of coding agents across sequential real-world tasks by pruning irrelevant tools, injecting micro-skills, and interrupting failure loops.

MicrosoftResearch Microsoft Research · Oct 15, 2026

TradingAgents: Multi-Agents LLM Financial Trading Framework

A multi-agent framework using large language models for stock trading simulates real-world trading firms, improving performance metrics like cumulative returns and Sharpe ratio.

  • 4 authors
· Dec 28, 2024
Submitted by
ruiyaox

Harness^2: Recursive Agent Harnessing for an Open World

Harness² improves agent execution harnesses through recursive task-level refinement and continual harness-level learning, boosting performance across benchmarks without ground-truth verifiers.

google Google · Oct 9, 2026
Submitted by
bupalinyu

The Other Half of the Memory Wall: Serving 35B MoEs from SSD with Trained Routing Prediction

Edge0 enables efficient mixture-of-experts inference on consumer hardware by predicting expert routing ahead of time and using recovery adapters to maintain quality with minimal active memory.

Edge0 Edge0 · Sep 16, 2026
Submitted by
taesiri

Unlimited OCR Works

Unlimited OCR introduces Reference Sliding Window Attention to eliminate growing memory consumption during long-sequence OCR tasks, enabling efficient transcription of multiple pages in a single forward pass.

baidu BAIDU · Jun 22, 2026
Submitted by
taesiri

AgentScope 1.0: A Developer-Centric Framework for Building Agentic Applications

AgentScope enhances agentic applications by providing flexible tool-based interactions, unified interfaces, and advanced infrastructure based on the ReAct paradigm, supporting efficient and safe development and deployment.

  • 23 authors
· Aug 22, 2025
Submitted by
akhaliq

Very Large-Scale Multi-Agent Simulation in AgentScope

Enhancements to the AgentScope platform improve scalability, efficiency, and ease of use for large-scale multi-agent simulations through distributed mechanisms, flexible environments, and user-friendly tools.

  • 8 authors
· Jul 25, 2024
Submitted by
caiyuchen

Investor's Last Exam: Can AI Agents Do Equity Investment Without Seeing the Future?

Investor's Last Exam evaluates financial agents on end-to-end equity research using frozen evidence, expert criteria, and dependency graphs, revealing that top models excel at research but fail at forecasting and investment judgments.

  • 10 authors
· Oct 28, 2026

Kronos: A Foundation Model for the Language of Financial Markets

Kronos, a specialized pre-training framework for financial K-line data, outperforms existing models in forecasting and synthetic data generation through a unique tokenizer and autoregressive pre-training on a large dataset.

  • 7 authors
· Aug 2, 2025
Submitted by
Phospheneser

MOSS-Image Technical Report

MOSS-Image is an open diffusion transformer that combines high-fidelity synthesis with intent-aware prompt enhancement to generate text-rich, layout-coherent images, achieving state-of-the-art open-weight results on long-form text and layout benchmarks.

OpenMOSS-Team OpenMOSS · Oct 16, 2026
Submitted by
akhaliq

OpenDevin: An Open Platform for AI Software Developers as Generalist Agents

OpenDevin is a platform for developing AI agents that interact with the world by writing code, using command lines, and browsing the web, with support for multiple agents and evaluation benchmarks.

  • 24 authors
· Jul 23, 2024
Submitted by
akhaliq

Efficient Memory Management for Large Language Model Serving with PagedAttention

PagedAttention algorithm and vLLM system enhance the throughput of large language models by efficiently managing memory and reducing waste in the key-value cache.

  • 9 authors
· Sep 12, 2023
Submitted by
SempraETY

Intrinsic Distribution Matching

Intrinsic Distribution Matching improves few-step text-to-image generation by adding explicit moment constraints to distribution matching distillation, achieving state-of-the-art long-text rendering with minimal network evaluations.

inclusionAI inclusionAI · Oct 29, 2026
Submitted by
weizhiwang

Hy-Nomas: Towards Free-form Interactive World Generation

Hy-Nomas is a video world model that uses causal attention and structured conditioning to generate interactive, multi-turn video segments with text and camera control.

Tencent-Hunyuan Tencent Hunyuan · Oct 27, 2026
Submitted by
lgy0404

nanoMuse: An Open-Source Personal Agent for Every Device You Own

Assistants from 2011 answered and waited, and agents from 2023 did a task and stopped. In September 2026 Meta's Muse showed an agent for one person, with accounts, devices, memory and a conversation that lasts, closed, in a vendor's cloud, in one country. Such an agent is expected to act on a person's accounts and devices, remember them across weeks, speak first when it is worth it, and answer for what it did. It is a kind of software, not a model, and until now had no open counterpart. This report defines the personal agent in five questions and three horizons. It reads how Muse is built from Meta's public record and a copy of its production prompt, each statement marked by its source. It then presents nanoMuse, the open-source counterpart under the GPL-3.0, one agent on every device a person owns, with hands on the phone's screen and the computer's. They share one conversation over a relay anyone can run; every action goes through a Sentinel, memory is files the person can read, and the model is their choice. Its size and cost are given as estimates. What is open, memory with provenance, an evaluation suite for the hands and an open model for them, is set out as a roadmap.

zju Zhejiang University · Oct 6, 2026
Submitted by
taesiri

MinerU2.5: A Decoupled Vision-Language Model for Efficient High-Resolution Document Parsing

MinerU2.5, a 1.2B-parameter document parsing vision-language model, achieves state-of-the-art recognition accuracy with computational efficiency through a coarse-to-fine parsing strategy.

  • 61 authors
· Sep 26, 2025
Submitted by
andito

SmolDocling: An ultra-compact vision-language model for end-to-end multi-modal document conversion

SmolDocling is a compact vision-language model that performs end-to-end document conversion with robust performance across various document types using 256M parameters and a new markup format.

ibm-granite IBM Granite · Mar 14, 2025
Submitted by
akhaliq

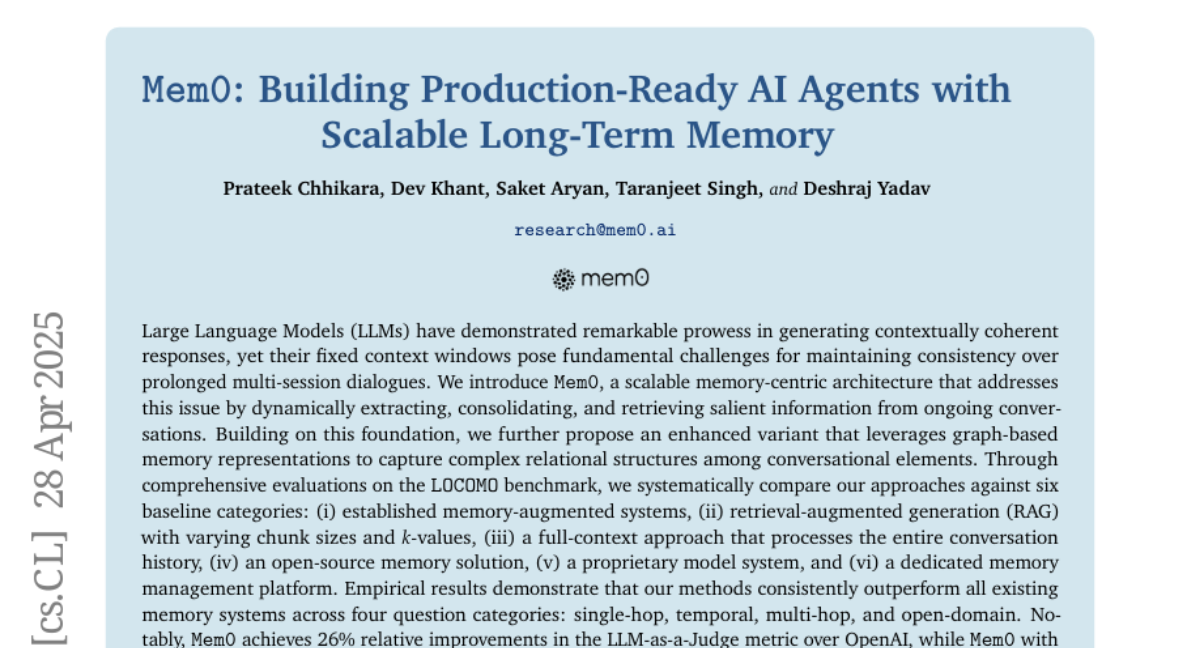
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory

Mem0, a memory-centric architecture with graph-based memory, enhances long-term conversational coherence in LLMs by efficiently extracting, consolidating, and retrieving information, outperforming existing memory systems in terms of accuracy and computational efficiency.

  • 5 authors
· Apr 28, 2025
Submitted by
kumboh

Next-Concept Modeling: Fast, Parallel Coarse-to-Fine Text Generation

Next-Concept Modeling uses hierarchical discrete codes and parallel level-wise generation to accelerate diffusion language models while improving quality and reasoning performance.

StanfordUniversity Stanford University · Oct 9, 2026
Submitted by
hyz317

HairDeck: Animation-Ready Stylized Hair Cards from a Single Image

HairDeck generates stylized hair cards and spring-bone animations as unordered token sets using a diffusion transformer, improving accuracy and speed over prior methods.

Tsinghua Tsinghua University · Oct 29, 2026
Submitted by
ChengCui

PaddleOCR-VL-1.6: Expanding the Frontier of Document Parsing with Under-Optimized Region Refinement and Progressive Post-Training

PaddleOCR-VL-1.6 enhances document parsing performance through targeted data optimization and progressive post-training techniques, achieving state-of-the-art results on OmniDocBench v1.6.

PaddlePaddle PaddlePaddle · Jun 2, 2026

Xiaomi-OCR-0 Technical Report

Xiaomi-OCR-0 is a compact vision-language model that unifies document parsing and OCR understanding through automated data synthesis, progressive training with text anchoring and reinforcement learning, and achieves state-of-the-art results on multiple benchmarks.

  • 10 authors
· Sep 28, 2026
Submitted by
RuofengYang

ARIS: Autonomous Research via Adversarial Multi-Agent Collaboration

ARIS is an open-source research harness that uses cross-model adversarial collaboration to ensure reliable long-term research outcomes through coordinated execution, orchestration, and assurance layers.

Submitted by
FrancisRing

Prism: Dynamic Sparse Attention for Native 2K Joint Video-Audio Generation Model Training

Prism accelerates native joint video-audio generation at 2K by using dynamic sparse attention guided by local visual variance and audio-visual cross-attention to preserve semantic coherence and cross-modal interactions.

Tencent-Hunyuan Tencent Hunyuan · Oct 4, 2026
Submitted by
liangtm

WeVisOne-VL: Unified Visual Perception from Objects to Pixels

WeVisOne-VL unifies object-level and pixel-level visual perception via structured token prediction, supporting detection, localization, counting, OCR, segmentation, and matting with a lightweight pixel decoder and multi-stage training.

tencent Tencent · Oct 22, 2026

Internal Safety Collapse in Frontier Large Language Models

Frontier large language models exhibit Internal Safety Collapse, where they generate harmful content under specific task conditions, revealing inherent vulnerabilities despite alignment efforts.

  • 10 authors
· Mar 4, 2026
Submitted by
LIQIIIII

DynaFlow: Learning Free-Form Multi-Agent Orchestration

DynaFlow enables adaptive multi-agent collaboration by letting a main agent synthesize executable workflows that coordinate sub-agents through structured execution and verification.

Submitted by
a43992899

YuE2: Unifying Symbolic and Audio Music Generation at Frontier Quality

YuE2 unifies symbolic and audio music generation via symbolic planning, producing readable scores and full-song audio with state-of-the-art quality and agentic editing capabilities.

Submitted by
nielsr

Geometric Context Transformer for Streaming 3D Reconstruction

LingBot-Map is a feed-forward 3D foundation model that reconstructs scenes from video streams using a geometric context transformer architecture with specialized attention mechanisms for coordinate grounding, dense geometric cues, and long-range drift correction, achieving stable real-time performance at 20 FPS.

robbyant Robbyant · Apr 15, 2026

HuggingFace's Transformers: State-of-the-art Natural Language Processing

Transformers library provides state-of-the-art Transformer architectures and pretrained models for natural language processing tasks with a unified API and emphasis on extensibility and robust deployment.

huggingface Hugging Face · Oct 9, 2019
Submitted by
Lingaaaaaaa

RSI-Anything: Unlocking Recursive Self-Improvement with World Models

RSI-Anything leverages predictive world models to guide action selection and adaptive learning, enabling recursive self-improvement across coding, interface navigation, laboratory planning, and scientific optimization tasks.

PhAILabs PhAI Labs · Oct 9, 2026
Submitted by
RandallBalestriero

Proving and Improving the Platonic Representation Hypothesis with JEPAs

Joint-embedding predictive architectures trained on aligned multi-modal observations converge to shared representations with far greater efficiency than next-token prediction, demonstrating that positive view design—not scale alone—drives cross-modal alignment.

galilai-group galilai-group · Oct 29, 2026
Submitted by
Rizling

Build, Don't Play: Self-Improving LLM Research Agents Develop a Hearthstone Battlegrounds AI That Rivals Top Players

AutoTavern demonstrates that self-improving LLM research agents can autonomously build a faithful game simulator and train a reinforcement learning agent that surpasses top human players in Hearthstone Battlegrounds.

Submitted by
Gokottaw434

Read, Allocate, Route: Role-Coupled Tokenization for Pixel-Space Generative Transformers

SpecSlot improves pixel-space generative Transformers by using localized spectral slots and restricted global attention to increase image detail without raising computational cost.

  • 5 authors
· Oct 29, 2026
Submitted by
jasonrqh

COLLEAGUE.SKILL: Automated AI Skill Generation via Expert Knowledge Distillation

Person-grounded AI skills are automatically distilled from heterogeneous traces into inspectable, correctable packages that capture both capabilities and behavioral patterns.

ShanghaiAiLab shanghai ailab · May 29, 2026
Submitted by
Rbin

RAG-Anything: All-in-One RAG Framework

RAG-Anything is a unified framework that enhances multimodal knowledge retrieval by integrating cross-modal relationships and semantic matching, outperforming existing methods on complex benchmarks.

Submitted by
liamdugan

Building Auditable AI Text Detectors with Sparse Autoencoders

A pipeline using sparse autoencoders extracts interpretable linguistic features from neural detectors, yielding more accurate and explainable AI-generated text classification.

GoogleDeepMind GoogleDeepMind · Oct 21, 2026
Submitted by
Jungang

StreamEval: Evaluating Interactive Streaming Video Generation Models

StreamEval benchmarks interactive streaming video generation across five tasks, revealing that reliable request execution and sustained state consistency remain major challenges despite high visual quality.

  • 1 authors
· Oct 20, 2026

OmniFlatten: An End-to-end GPT Model for Seamless Voice Conversation

A novel GPT-based model, OmniFlatten, enables real-time natural full-duplex spoken dialogue through a multi-stage post-training technique that integrates speech and text without altering the original model's architecture.

  • 9 authors
· Oct 23, 2024

PDFMathTranslate: Scientific Document Translation Preserving Layouts

PDFMathTranslate enables layout-preserving scientific document translation using large language models and precise layout detection, offering improved precision, flexibility, and efficiency.

  • 4 authors
· Jul 2, 2025
Submitted by
shenjunhao

Work Agents: Systems, Capabilities, and Optimization

The paper proposes a unified framework for work agents that integrates foundation models with runtime harnesses to execute complex digital tasks reliably, introducing dimensions of persistence and openness alongside capability families and evaluation metrics.

Submitted by
Linzhan

UniMate: One Unified Model to Animate Diverse Skeletons

UniMate is a unified diffusion transformer that generates articulated motion for arbitrary skeletons from text and rigged 3D assets without per-skeleton retraining, using topology-aware attention and a large curated motion dataset.

princetonu Princeton University · Sep 4, 2026

Bitnet.cpp: Efficient Edge Inference for Ternary LLMs

Bitnet.cpp enhances edge inference for ternary LLMs using a novel mixed-precision matrix multiplication library, achieving significant speed improvements over baselines.

  • 10 authors
· Feb 17, 2025

Zep: A Temporal Knowledge Graph Architecture for Agent Memory

Zep, a memory layer service, outperforms MemGPT in the DMR benchmark and LongMemEval by excelling in dynamic knowledge integration and temporal reasoning, critical for enterprise use cases.

  • 5 authors
· Jan 20, 2025
Submitted by
lhpku20010120

OmniEdu: Open Foundation Models for Learning and Teaching

OmniEdu is a family of instruction-tuned educational foundation models that improve K-12 problem solving, curriculum understanding, and tutoring through capability-balanced training data.

PekingUniversity Peking University · Sep 19, 2026
Submitted by
supra3d

SUPRA-TEX: 3D Generation with Super-Aligned Texture

SUPRA-Tex decouples visible-material estimation, surface alignment, and 3D completion to generate relightable 3D materials that preserve reference image details and complete unobserved surfaces.

  • 8 authors
· Oct 15, 2026
Submitted by
Awesome-GraphRAG

Zero-Mem: Zero-Token Memory Operations for LLM Agents

Zero-Mem enables structured agent memory without intermediate LLM generation by organizing interaction traces into complementary graph and temporal views for deterministic retrieval.

  • 11 authors
· Jul 31, 2026
Submitted by
Qinsi1

InteractiveWorld: A Verifiable Human-Centric Environment for Building Better Interactive MLLM Assistants

InteractiveWorld provides a verifiable simulation environment and benchmark to evaluate whether multimodal language models can reliably guide humans through physical tasks.

meta Meta · Oct 25, 2026
Submitted by
nielsr

Ultralytics YOLO26: Unified Real-Time End-to-End Vision Models

YOLO26 addresses real-time vision challenges through a unified model family with NMS-free inference, improved training strategies, and multi-task capabilities spanning detection, segmentation, and pose estimation.

Ultralytics Ultralytics · Jun 2, 2026
Submitted by
yifAI

Recurrent Looped Transformer

The Recurrent Looped Transformer uses a recurrent decoder with feedback to grow computation depth per token, enabling strong generalization on parity, permutation tracking, and modular arithmetic tasks.

princetonu Princeton University · Oct 6, 2026